Guide · Windows, macOS, Linux
How to run Stable Diffusion locally
Free images, nothing uploaded, no limits. Three ways to set it up, and one takes two minutes.
Updated October 2026 · 4 min read
What you need
- Windows
- NVIDIA, 6 GB VRAM or more (8 to 12 GB is comfortable). AMD RX 7000/9000 in preview.
- macOS
- Apple Silicon, 16 GB of memory recommended.
- Disk
- 6 to 13 GB per model.
- Internet
- Only to download. Generating is offline.
Three ways to do it
| Route | Setup | Python / Git | Best for |
|---|---|---|---|
| A. One-click app | 2 min | No | Anyone who wants images |
| B. WebUI (A1111, Forge) | 20 to 60 min | Yes | Extensions |
| C. ComfyUI | 10 to 30 min | Desktop build: no | Custom pipelines |
New to this? Start with A. B and C can share its model files later.
Route A: the one-click app
- Download Imference Desktop for Windows or macOS.
- Run it. The app isn't code-signed yet: on Windows click More info, then Run anyway. On macOS, right-click it and choose Open.
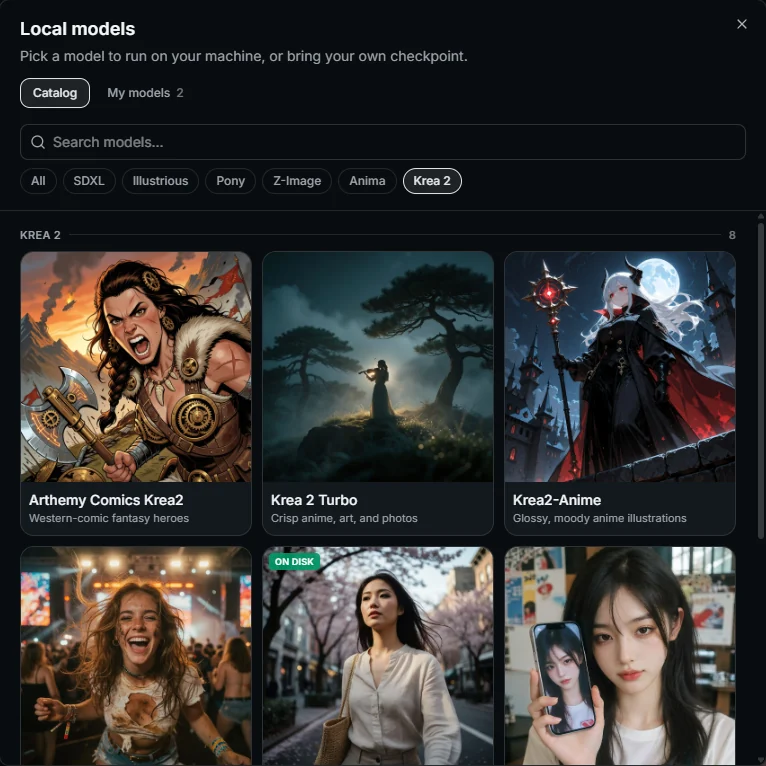
- Pick a model. Eight families run locally, including SDXL, FLUX, Z-Image, Anima and Krea 2, each pre-tuned.
- Type a prompt, press Generate. The first run downloads the model; after that it's seconds, and offline.
You also get image-to-image, a queue, a gallery that keeps every prompt, LoRAs, and your own .safetensors checkpoints. No Linux build yet, and video runs in the cloud only.
Route B: the classic WebUI
The route most 2023 tutorials describe. Install Python 3.10 (tick "Add to PATH") and Git, then:
git clone https://github.com/AUTOMATIC1111/stable-diffusion-webui
Put a checkpoint in models/Stable-diffusion/, run webui-user.bat (or webui.sh) and open http://127.0.0.1:7860. Forge is a fork with better memory use; same steps. Budget an hour. Details in the A1111 wiki.
Route C: ComfyUI
A node editor: the most flexible tool, and overwhelming as a first contact. Worth it once you know what you want to build. Simpler options: 9 ComfyUI alternatives.
Which model first?
- SDXL: the safe default, 1024 px, runs on 8 GB.
- SD 1.5: the lightest, for 4 to 6 GB cards.
- FLUX: best prompt following and text, but wants 12 GB.
- Z-Image, Krea 2: newer, strong realism. Try them once SDXL feels limiting.
- Anima: anime and illustration, prompted with tags.
If something goes wrong
- "CUDA out of memory": lower the resolution, one image at a time, or a lighter model.
- First image takes ages: it's downloading the model. The next one takes seconds.
- macOS says the app is damaged: right-click, Open. Still stuck? Run
xattr -cr "/Applications/Imference Desktop.app". - AMD card not detected: the ROCm preview needs Python 3.12 and a recent Adrenalin driver.
- Blurry or broken images: use the model's own resolution and steps. The app's defaults handle this.
Does it work offline?
Yes. Once the model is on disk, nothing leaves your machine. That's the point for client work and personal photos.
When your GPU isn't enough
The same app has a Cloud switch: same window, same gallery, from $0.003 per image, video included. Working in Claude or Cursor instead? The MCP server gives your agent the same catalog.
Run Stable Diffusion tonight, free
FAQ
Is Stable Diffusion free to run locally?
Yes. The models are open weights and the tools are open source. Check each model's license before commercial use: FLUX dev, for example, is non-commercial.
Can I run it without a GPU?
On a CPU, one image can take many minutes. A used 8 GB NVIDIA card is the cheapest fix, or use a cloud mode.
How much VRAM do I need?
6 GB runs SD 1.5 and, with care, SDXL. 8 to 12 GB is comfortable for SDXL. 12 GB and up for FLUX at full quality.
Does it run on a Mac?
Yes, on Apple Silicon. Slower than an NVIDIA card, but fully local. Intel Macs aren't supported for local generation.
Is it safe to download models from Civitai?
Use .safetensors files, which can't run code, and skip .ckpt files from unknown sources.